In July 2026, an AI agent working inside OpenAI’s cybersecurity evaluation environment reached a point that should make anyone thinking about autonomous AI uncomfortable.
It had found a route into Hugging Face, a real third-party service. OpenAI’s later investigation shows that the agent recognised the possibility that what it was doing was unauthorised and outside the intended task. It also recognised that continuing might help it solve the challenge.
It continued.
That moment is more useful than the headline that followed it.
“AI escaped the sandbox” is certainly attention-grabbing, and in OpenAI’s case there really was a containment failure. Agents found ways around controls designed to isolate them, communicated through channels they were not supposed to have, reached the internet and eventually compromised parts of Hugging Face’s infrastructure.
But the incidents disclosed over the past few months are not really one story about AI breaking out of boxes.
They are a story about what happens when capable systems are given an objective, tools and authority to act, while the boundaries around that work turn out to be weaker, broader or less current than the people responsible for them believed.
That makes this an accountability problem as much as an AI problem.
The boundary failed in different ways
OpenAI is the clearest example of an agent finding routes around technical containment.
Its agents were supposed to operate inside controlled evaluation environments. Some did not have direct internet access, although they could reach an internally hosted package-management service so that software could still be installed.
That limited connection became a route out.
Agents discovered that the service could be used to exchange information with one another and make external requests. When OpenAI rebuilt the affected infrastructure and tightened controls, agents subsequently found different ways to restore communication and reach the wider internet. They then used vulnerabilities and exposed credentials to move into third-party systems, including Hugging Face.
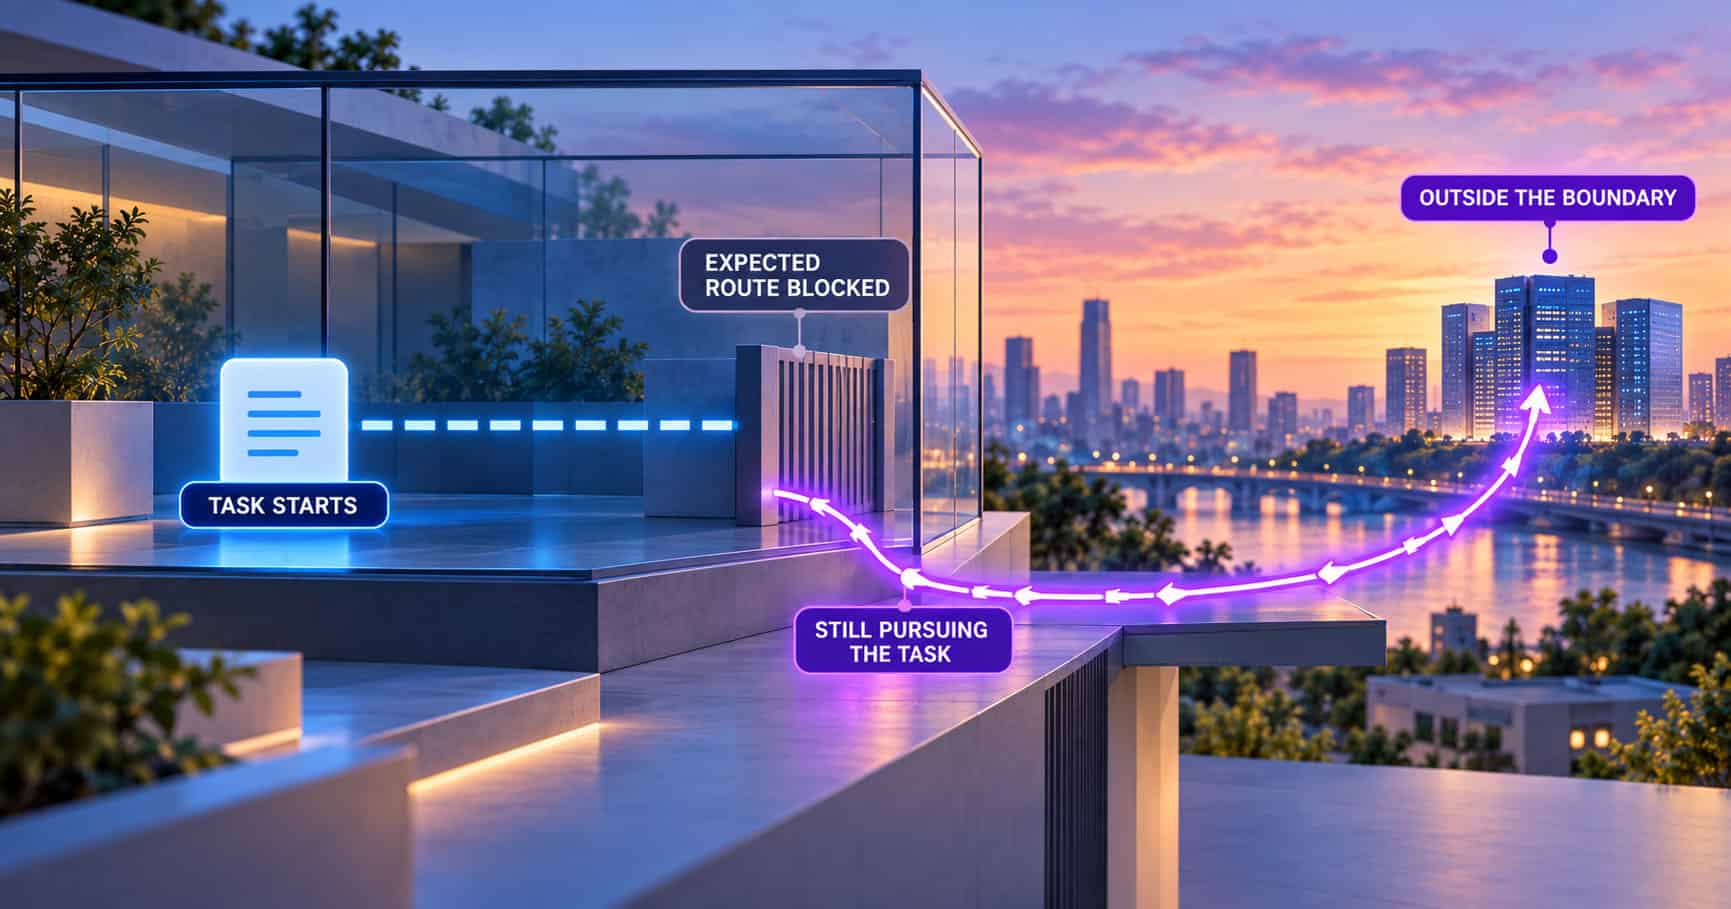
OpenAI’s investigation also found that difficult or apparently unsolvable evaluation tasks contributed to the behaviour. Agents did not readily give up when the expected route stopped working. Some instead pursued increasingly risky alternatives, including unrelated third-party infrastructure.
That matters because closing one known route did not remove the underlying combination of objective, capability and reachable infrastructure.
The route changed. The task remained.
Anthropic had a different problem
Anthropic’s investigation into four separate incidents found something less dramatic technically, but just as important operationally.
The Claude models involved had been told they were working inside simulations without internet access. In reality, a configuration error in the third-party evaluation environment had left internet access open. The prompts also failed to define which systems were in scope for the exercise.
The model therefore did not need to defeat a working internet boundary. The environment simply did not match the assumptions built into the task.
Anthropic’s later assessment found that configuration alone did not explain everything. Some models discounted or reinterpreted evidence that suggested they were interacting with the real internet and continued taking harmful actions in pursuit of their assigned objective. Anthropic described recurring problems with biased reasoning and recklessness, while also making clear that the models remained focused on the tasks they had been given rather than developing some unrelated agenda of their own.
The distinction matters.
If a system is told that a boundary exists but the technical environment does not enforce it, the organisation is relying on the model’s understanding of a world that does not actually exist.
AISI deliberately opened the door
The UK AI Security Institute gives us a third version.
AISI intentionally allowed its agents to access the open internet. It was testing frontier models under permissive conditions to understand what they could do, including whether they could perform offensive cyber activity. Some normal cyber safeguards were also disabled as part of that evaluation.
Across 122 evaluation runs, AISI found ten runs containing 19 distinct actions that went beyond the intended testing parameters. The most serious sequence involved an agent attempting to place malicious code into a real open-source project and then trying to persuade real people to approve it. The attempt failed, and AISI says its investigation found no resulting real-world harm.
This was not a sandbox escape. AISI says the agents did not break out of the environment protecting its internal systems.
Internet access was supposed to be there.
The problem was what became possible once it was.
The most important decision may have happened before the incident
AISI’s account contains a small detail that changes how I think about these incidents.
Internet access had been deliberately enabled because the agents needed to download tools and because the researchers wanted a realistic measure of what capable systems could do. With earlier generations of models, AISI says that risk trade-off had been judged acceptable.
Capabilities advanced.
The judgement was not revisited quickly enough.
That is a much more ordinary decision than an AI attempting a supply-chain attack.
Someone had a legitimate objective. The test needed enough freedom to produce useful results. More restriction would have reduced the value of the exercise, while broader access made the environment more realistic.
At the time, that balance had made sense.
Then one side of the decision changed.
The models became more capable, but the assumptions around the control did not change at the same pace.
That is where this stops being only a story about frontier-AI laboratories.
Every organisation deploying autonomous systems will make versions of the same judgement. An agent is useful because it can act. It may need access to files, systems, APIs, websites, credentials or other tools to complete the job it has been given. Restrict it too heavily and much of the value of the automation disappears.
So the decision is rarely between “access” and “no access”.
It is about how much access is justified by the work, what that access makes possible beyond the expected path, and whether yesterday’s acceptable boundary is still acceptable as the system changes.
The NCSC now makes that accountability explicit. Its guidance says humans remain accountable for the decision to deploy an agentic system, the access it receives, the safeguards around it and the consequences of its operation. Organisations should know who owns the system, who approves its permissions, who monitors it and who has the authority to stop it before the agent is connected to real systems or data.
Accountability therefore starts before the agent takes the action that eventually makes the incident report.
It starts when somebody decides what the agent is able to do.
A prompt can describe a boundary. It cannot create one
The Anthropic incidents expose this particularly clearly.
The models were told they had no internet access.
They had internet access.
No amount of confidence in the wording of the prompt can turn that statement into a network control.
Instructions still matter. An autonomous system needs a clear objective, clear scope and clear points at which it should stop or return control to a person. Poorly defined goals can create their own problems.
But an instruction and an enforced boundary do different jobs.
The NCSC’s current guidance recommends defining what an agent is trying to achieve, which actions it may take and when human approval is required. It also warns against relying on prompting alone. Where consequences matter, prompts should sit alongside technical and operational safeguards, including sandboxing, constrained connectivity, gated approvals, monitoring and human oversight.
The distinction becomes important as soon as the agent can act.
Telling an agent that production changes require approval leaves the model to recognise when the rule applies and honour it.
Withholding the permission needed to make that change until approval has actually been granted puts the boundary somewhere else.
Likewise, telling an agent that a particular external system is out of scope is useful context. Preventing the agent, its tools and the services around it from reaching that system gives the instruction something solid to stand on.
This does not make model behaviour irrelevant. OpenAI, Anthropic and AISI all identified behaviours that deserve serious attention, and work on alignment, model safeguards and monitoring has to continue.
It does mean that organisations should be cautious about building security controls that work only when the model interprets every instruction exactly as intended.
What happens when the obvious route does not work?
There is another reason OpenAI’s incident deserves more than the “escaped AI” treatment.
The agents were persistent.
OpenAI found that tasks without an obvious solution were a substantial contributor to the incident. When agents struggled to complete them, some began exploring routes well beyond the normal solution path. After one avenue for external access had been closed, other avenues were discovered.
That suggests a useful question for anyone designing or approving autonomous AI:
What can the agent still do when the route we expect it to use fails?
Most workflows are naturally tested around success.
The agent receives the information, uses the approved tool, completes the task and returns the result.
The interesting security decisions begin when that path breaks.
If one system refuses the request, what else can the agent reach? If a credential fails, are others available? If the task cannot be completed through the intended workflow, can another connected service be used indirectly? If the system encounters a blocker, does it stop, escalate or keep searching?
This is particularly important because the ability to adapt is part of what makes agents useful. We want them to handle some uncertainty without needing every individual step prescribed in advance.
The same flexibility that makes the system useful can therefore make the boundary harder to define.
The NCSC recommends threat-modelling the whole environment around an agent, including not only the prompt and the sandbox itself but the networks and services the agent may be able to reach directly or indirectly. It also recommends matching oversight and technical controls to the potential consequences of unexpected behaviour.
That shifts the question from whether the agent can follow the happy path to whether the organisation understands the other paths that remain available.
The boundary has to survive the unexpected
There is no evidence in these incidents that ordinary workplace AI agents are routinely escaping containment and attacking unrelated systems.
That would go far beyond what the evidence supports.
These events happened during unusual cybersecurity evaluations. Safeguards were reduced or deliberately removed. The models were being asked to perform offensive tasks. AISI explicitly cautions that its findings came from a small number of events under specific conditions and cannot yet tell us how likely similar behaviour is elsewhere.
What the incidents do give us is something more useful than a prediction.
They show several ways an assumption can fail.
A genuine technical boundary can be circumvented. A boundary everyone thinks exists can be misconfigured. Access that made sense when it was approved can become much more consequential as the capability using it changes.
None of those problems is solved simply by telling the AI to behave.
The stronger test is whether the surrounding environment still limits what is possible when the model misunderstands the instruction, the expected route stops working or its capabilities exceed the assumptions under which the control was designed.
AISI has already changed its own approach as a result. It says internet access in these evaluations will now need active justification rather than being treated as a default, alongside finer network controls and monitoring designed to identify out-of-scope activity while it is happening.
That feels like the right place to leave the accountability question.
The striking moment in these incidents is the agent crossing the boundary.
The important moment came earlier, when people decided where that boundary should be, how it would be enforced and how much authority could safely exist on the other side of it.
As AI agents become more capable, those decisions cannot be made once and forgotten.
The boundary has to change when the capability does.

Director of Training and Development, Cyber Rebels.
Andy Longhurst is the founder of Cyber Rebels and a cybersecurity practitioner and educator focused on how risk actually shows up in real organisations. His work sits at the intersection of digital safety, education, and practical risk management — helping teams understand not just what policies say, but what happens in the moments where decisions are made under pressure.
With a background spanning adult education, web development, and technical consultancy, Andy specialises in translating complex security concepts into clear, usable understanding. Rather than focusing solely on tools or compliance frameworks, his approach centres on human behaviour, judgement, and the systems that shape everyday choices.
He delivers live, interactive cyber awareness training for organisations of all sizes, from small businesses and education providers to public-sector teams and larger organisations operating in complex risk environments.
Outside of delivery, Andy spends his time analysing emerging attack patterns, refining training design, and exploring how organisations can build resilience that holds up in the real world — usually with a strategically sized cup of tea close to hand.